Skip to content
    Token FactoryAgentOSDedicated GPUsAI Factory

    The platform beneath agent-native AI

    Inference, fine-tuning and pre-training on one control plane. Any runtime, any model, multiple accelerators.
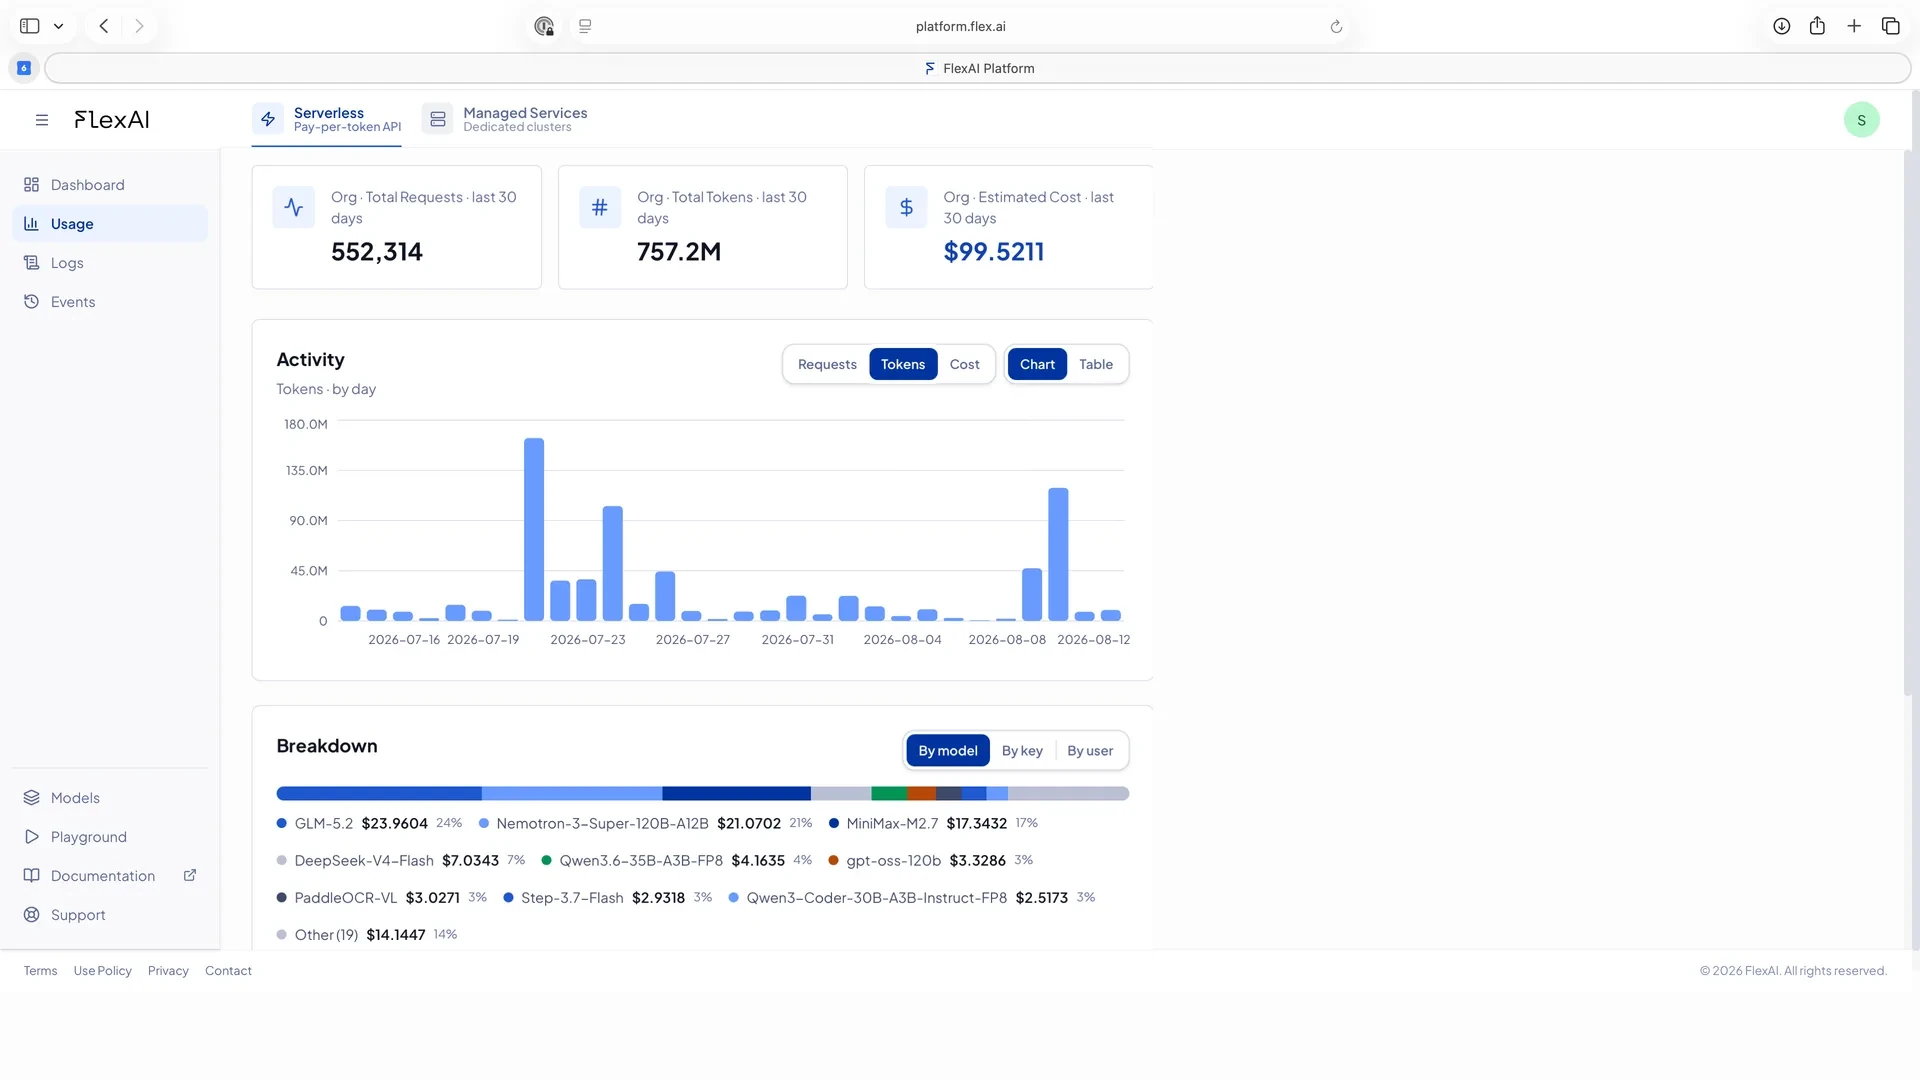
    FlexAI platform usage view: 552,314 requests and 757.2M tokens over 30 days, with cost broken down per model.

    Consumption attributed per model, per key and per user, against the organization rate ceiling.

    Grow and scale on one account

    Start small, scale to private cloud

    Start on a key, move to Dedicated GPUs when volume pays off, and land in your own boundary without re-platforming.

    InferenceServing to traffic
    Token FactoryPer tokenOne key, every model we serve serverless, no capacity to plan.
    Dedicated GPUsDedicated endpointsProduction inference on GPUs that serve only your traffic, autoscaling to zero, billed per minute.
    AI FactoryIn your perimeterThe same serving stack, VPC to air-gapped.
    Fine-tuningAdapting to your domain
    Starts at dedicated capacity
    Dedicated GPUsManaged runsSFT, DPO with LlamaFactory, GRPO with EasyR1, evaluation with lm-evaluation-harness, deploy from the console or CLI.
    AI FactoryData stays putThe same workflow where your data already lives.
    Pre-trainingTraining from scratch
    Starts at dedicated capacity
    Dedicated GPUsMulti-nodeYour storage, auto-checkpointing, recovery mid-run.
    AI FactoryOn your clusterThe same training plane on hardware you own.
    DevelopmentBuilding and testing
    Starts at dedicated capacity
    Dedicated GPUsGPU VMs or containersSSH in, start from a tested blueprint, keep your work on persistent storage.

    AgentOS. Maestro UI, CLI, API, SDK, shell and Slack onto one runtime. Portable skills, scoped memory, governed tools and model council based routing across models.

    In trial
    Models, runtimes and hardware

    No lock-in

    You choose your models and deployment boundary. FlexAI optimizes execution within your choices.

    A stack diagram. At the top, your code makes one unchanged OpenAI-compatible call. Below a swap line sit three interchangeable layers: the model you choose, and the runtime and accelerator FlexAI optimizes within your choices.

    Your code

    POST /v1/chat/completions

    The model string is the only variable.

    1. 1ModelModel-independent
      • 744B sparse MoE
      • 27B dense VLM
      • your fine-tunes

      Sizing is derived per model, never tiered into instance classes, and the context on a model page is the window that model is configured to serve.

    2. 2RuntimeRuntime-independent
      • vLLM
      • SGLang
      • Triton
      • Custom

      Prefill and decode split onto separate capacity, so a long prompt never holds a decode slot. Precision, tensor parallelism, KV strategy and speculative decoding are per-model decisions. When no engine fits, we build one.

    3. 3AcceleratorHardware-independent
      • NVIDIA
      • AMD
      • Tenstorrent

      CUDA, ROCm and TT-Metal today, on owned and partner capacity.

    Runtimes, frameworks and tools

    A supported matrix across architectures and versions so tenants can run workloads without hand built images per cluster.

    Accelerators
    NVIDIAAMDTenstorrent
    Architectures
    CUDAROCmTT-Metal
    Precisions
    FP8NVFP4MXFP4BF16FP16FP32
    Inference engines
    vLLMSGLangTritonCustom
    Fine Tuning & Training
    PyTorchAxolotlLlamaFactoryTRLDeepSpeed
    Observability & Tools
    GrafanaPrometheusTensorBoardWeights & Biases

    How we run heterogeneous compute

    Platform modules

    Module Detail

    Infrastructure management

    • Unified management of GPU, CPU, memory, storage, and network resources across heterogeneous environments.
    • Provision GPUs as bare metal nodes or VM based environments depending on workload requirements.
    • Integrated cluster management supporting Kubernetes and Slurm for AI and HPC workloads.
    • Consistent resource abstractions across mixed hardware pools and infrastructure providers.
    • Built-in observability with real-time health metrics and resource utilization dashboards.
    Ready to clone

    Blueprints that turn weeks into minutes

    Ready-to-run templates for inference, fine-tuning and batch jobs.

    Want the platform walkthrough?
    How our managed AI Services connect to optional infrastructure blocks.