Inference that lets you ship a feature
Run open models serverless or on Dedicated GPUs, through one OpenAI-compatible API.
curl https://api.flex.ai/v1/chat/completions \
  -H "Authorization: Bearer $FLEXAI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "Meta-Llama-3.1-8B-Instruct-FP8",
    "messages": [{"role": "user", "content": "Hello from FlexAI"}]
}'Built for agent loops
The inference API gives your agent the primitives; AgentOS adds the run-level controls.
From the inference API
- ✓ Tool calls
- ✓ Structured output
- ✓ Streaming
- ✓ Model fallback
One API shape, serverless or dedicated
Start on shared per-token endpoints. When steady volume justifies your own GPUs, move to Dedicated GPUs on the same OpenAI-compatible API: point your client at your endpoint URL and key.
import os
from openai import OpenAI

client = OpenAI(
    base_url="https://api.flex.ai/v1",
    api_key=os.environ["FLEXAI_API_KEY"],
)

response = client.chat.completions.create(
    model="Meta-Llama-3.1-8B-Instruct-FP8",
    messages=[{"role": "user", "content": "Hello"}],
)
Production visibility without guesswork
Live usage metrics
Latency, tokens, GPU, region, cache. In one view.
Autoscaling
Scale replicas between your min and max, down to zero.
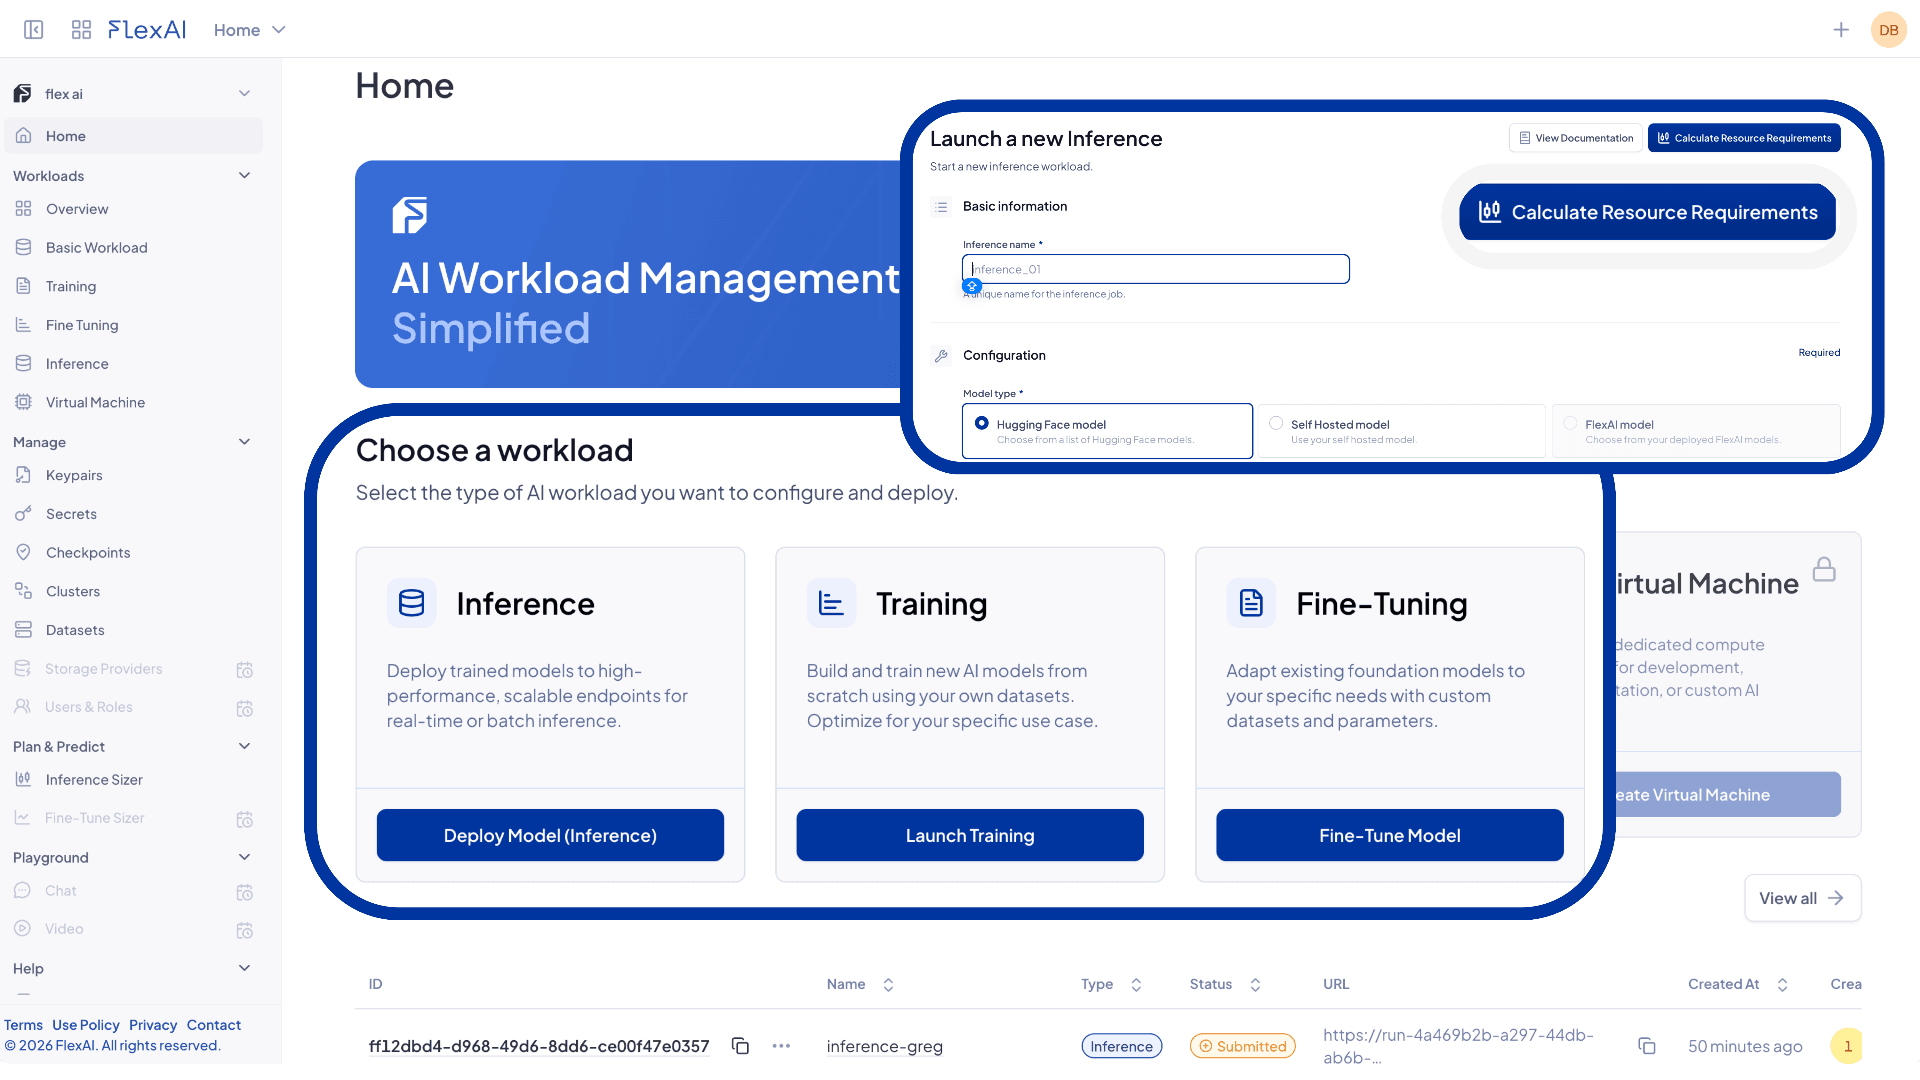
Production ready blueprints
Start with one endpoint
Sizing a workload? Compare costs in the GPU savings calculator or see Dedicated GPUs for dedicated capacity.
Frequently Asked Questions
FlexAI is optimized for low-latency streaming inference. Actual latency depends on model, context length, hardware, region, and traffic pattern.
FlexAI automatically scales GPU endpoints based on request volume. Endpoints scale between the min and max replicas you set, down to zero. You pay per minute for running replicas, and nothing when they scale to zero.
Any model that runs on vLLM, SGLang, Triton or a custom container, including your own fine-tunes.
More managed AI services: fine-tuning, training, and the platform overview.